Server performance is one of the most critical factors in keeping websites, applications, and online services running reliably. Whether you manage a Linux VPS for a business or host multiple client projects, you will encounter a metric called load average. At first glance, the values may seem opaque — you might see figures like 0.25, 1.80, 5.60, or even 15.30 and be uncertain whether the server is operating healthily or is under strain.
Understanding these numbers enables you to identify performance trends before they escalate into serious problems. Rather than reacting when slowness is already apparent, load average gives you a time-series view of how busy the operating system has been, allowing for informed, proactive decisions.
This guide explains what server load average is, what the 1-minute, 5-minute, and 15-minute values represent, how to interpret them accurately, and when they warrant further investigation.
What Is Server Load Average?
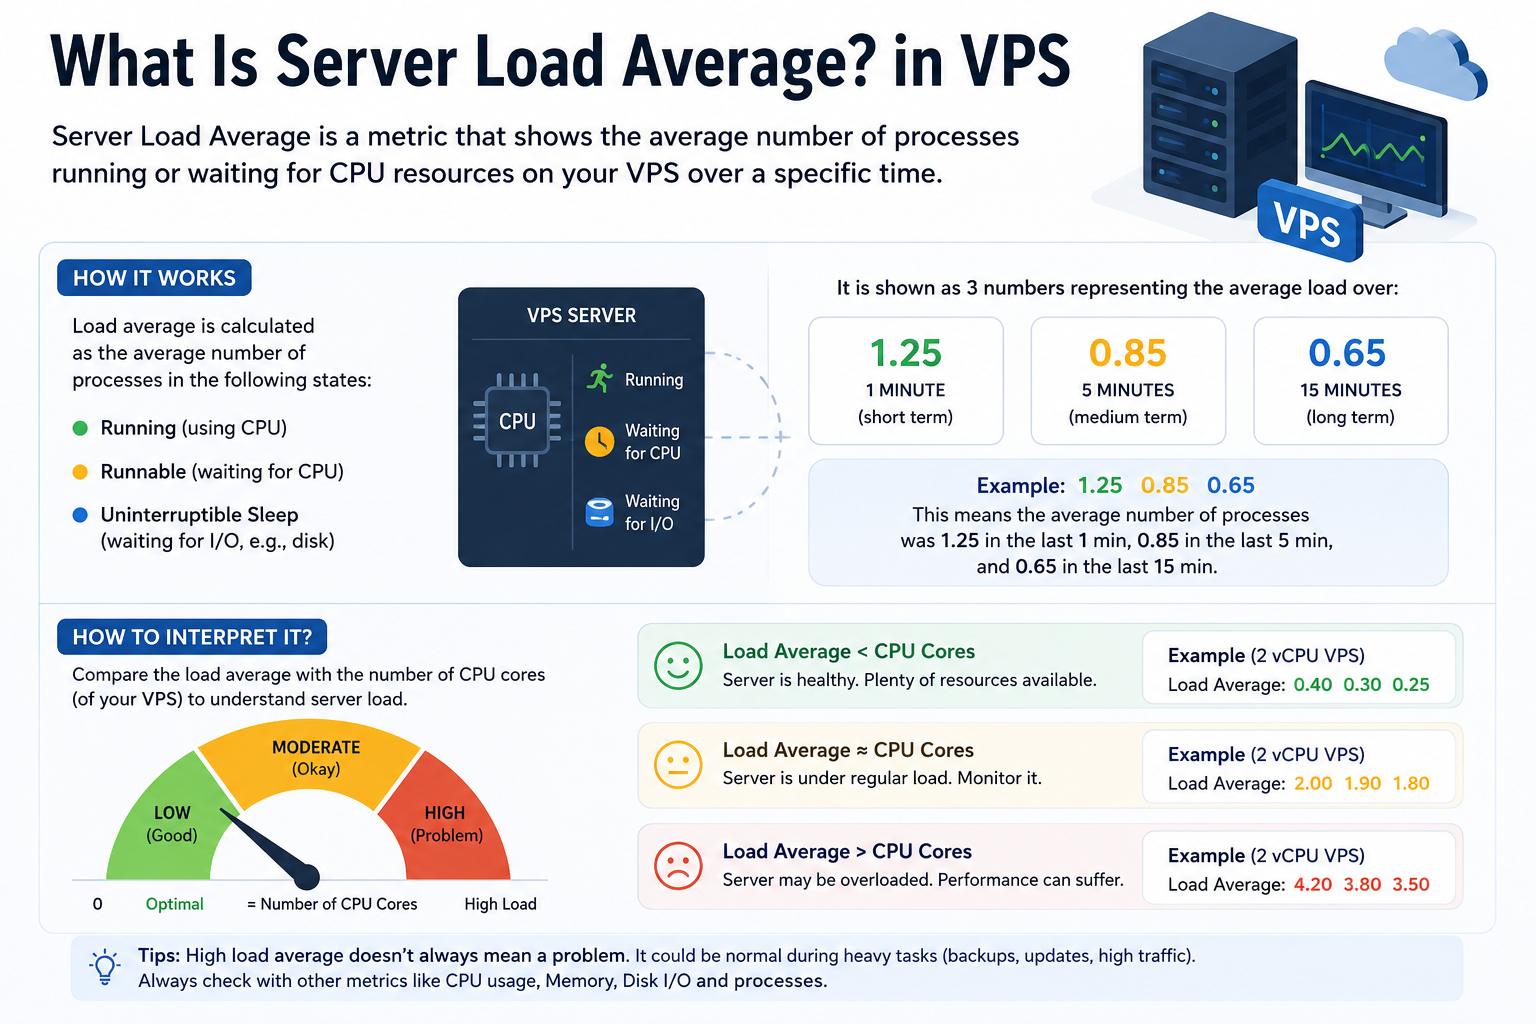
Load average measures the average number of processes that are either actively using system resources or waiting for them, calculated over a set time interval.
Important distinction for Linux: Unlike traditional Unix systems, which counted only processes waiting for CPU time, Linux load average includes processes waiting for I/O operations — such as disk reads and writes or network activity — in addition to CPU-bound processes. This means a high load average does not necessarily indicate CPU saturation; it may reflect I/O bottlenecks instead.
Unlike CPU utilization, which captures processor activity at a single instant, load average reflects sustained system demand over time.
A useful analogy: think of a supermarket checkout lane.
- One cashier = one CPU core
- Customers = running processes
- No queue means the system is operating comfortably
- A growing queue means more work is arriving than can be immediately serviced
Load average quantifies this queue depth over time.
Understanding the Three Load Average Values
Running the following command:
uptime
produces output similar to:
15:42:10 up 12 days, 4:16, 2 users, load average: 0.45, 0.72, 0.81
The three numbers correspond to three different time horizons:
Value | Time Horizon |
First | Last 1 minute |
Second | Last 5 minutes |
Third | Last 15 minutes |
Technical note: These are not simple arithmetic averages over fixed windows. They are exponentially-damped moving sums calculated from a five-second kernel sample rate, using 1, 5, and 15 as decay constants. In practice, the “1-minute” average reflects some influence from activity beyond the last 60 seconds, and it typically takes longer than one minute to reach a stable new value. This design filters out momentary noise while still responding meaningfully to recent changes.
These three values together reveal whether system demand is increasing, decreasing, or holding steady.
The 1-Minute Load Average
The first value is the most reactive. It responds quickly to recent activity such as:
- Backup jobs initiating
- Software updates or package installs
- Sudden traffic spikes
- Scheduled maintenance tasks
- Short bursts of application activity
Because it fluctuates rapidly, it should not be used in isolation to judge overall server health.
Example:
2.8 1.1 0.7
The server experienced a recent workload increase. Since the 5-minute and 15-minute values remain lower, this is likely a transient spike rather than a sustained problem.
The 5-Minute Load Average
The second value smooths out brief spikes and provides a more representative picture of ongoing demand.
If the 5-minute value is close to the 1-minute value, the system has been consistently busy. For many administrators, this is the most actionable indicator of current system state.
Example:
1.8 1.7 1.6
This indicates a steady, sustained workload — not a brief anomaly.
The 15-Minute Load Average
The third value reflects long-term system behavior. Because it changes slowly, it is most useful for identifying persistent load rather than reacting to temporary events.
If all three values remain elevated over an extended period, the server deserves closer examination.
Example:
4.9 4.8 4.7
The system has been under heavy load for at least fifteen minutes.
Reading Trends Across All Three Values
Using multiple time horizons allows you to understand direction, not just magnitude.
Pattern | Interpretation |
6.2 2.9 1.3 | Load is increasing rapidly |
1.4 3.5 5.8 | Load is decreasing — was higher earlier |
2.5 2.5 2.5 | Load has been stable over time |
Tracking trends is generally more actionable than reacting to any single reading.
How CPU Core Count Affects Interpretation
Load average must always be interpreted relative to the number of available CPU cores.
System | Full Utilization Threshold |
Single-core | 1.00 |
Dual-core | 2.00 |
Quad-core | 4.00 |
Eight-core | 8.00 |
A load of 3.0 may be excessive on a single-core server but entirely normal on an eight-core system. There is no universal “good” or “bad” load average — context is essential.
To check the number of logical CPU cores on your system:
nproc
What Is Considered Normal?
Normal load averages depend on:
- Number of CPU cores
- Type of workload (CPU-bound vs. I/O-bound)
- Running applications and their concurrency model
- Time of day and scheduled background tasks
General guidance:
- Load significantly below core count → comfortable headroom
- Load near core count → efficient utilization
- Load consistently above core count → processes may be queuing; investigate
Isolated spikes are common and expected. Persistent elevation is what warrants attention.
Common Causes of Temporary Spikes
Many Linux servers experience routine load increases throughout the day. Typical causes include:
- Cron jobs and scheduled scripts
- Log rotation
- Automated backups
- Package updates
- Database maintenance operations
- Search indexing
- Application deployments
If the 1-minute average rises while the 5-minute and 15-minute values remain low, the server is likely handling routine background activity with no cause for concern.
When to Investigate
Sustained high load deserves attention, particularly when users begin reporting degraded response times.
Warning signs include:
- All three load averages continuing to rise
- Load remaining above core count for extended periods
- Websites responding slowly
- SSH sessions becoming sluggish
- Application timeouts or unresponsiveness
- Scheduled tasks taking significantly longer than usual
Before concluding the CPU is the bottleneck, verify the cause. Because Linux load average includes I/O wait, a high reading may indicate disk or network saturation rather than CPU exhaustion. Checking CPU utilization separately (via mpstat or the %wa field in top) helps distinguish between the two.
How to Check Load Average
Linux provides several built-in tools:
uptime — quickest single-line view:
uptime
top — real-time process view with load averages in the header:
top
htop — interactive, color-coded interface (may require installation):
htop
w — shows logged-in users alongside current load:
w
/proc/loadavg — raw kernel output, useful for scripting:
cat /proc/loadavg
The output includes the three load averages, currently running process count, total process count, and the PID of the most recently created process.
Common Misunderstandings
“High load always means the CPU is overloaded.” Not necessarily. On Linux, load average includes processes waiting for I/O. The CPU may be largely idle while disk or network operations are the actual bottleneck.
“One high reading means something is wrong.” A single spike is usually harmless. Long-term trends are what matter.
“Load average should always stay below 1.” Only on a single-core system. Multi-core servers support proportionally higher values.
“Load average tells the whole story.” It is one indicator among many. A complete performance assessment includes CPU utilization, memory consumption, I/O wait times, and application-level metrics.
Best Practices for Monitoring Load Average
- Compare load against core count, not against an absolute threshold
- Observe trends across all three values rather than reacting to individual readings
- Monitor during peak traffic periods to establish a baseline
- Record historical values so you can identify gradual drift
- Investigate sustained increases, not brief spikes
- Correlate with CPU utilization and I/O metrics to identify the actual bottleneck
Frequently Asked Questions
