Linux error logs are among the most valuable tools for diagnosing problems on a VPS. When a website stops responding, SSH connections fail, a service crashes, or an application starts returning errors, logs can provide the timeline and evidence needed to determine what happened.
The challenge is not simply finding an error message. The real skill is knowing which logs to check, how to filter them, how to correlate events, and how to distinguish the root cause from a symptom.
This guide explains how to read and investigate Linux error logs on a VPS using practical commands, with examples for systemd, Nginx, Apache, PHP-FPM, SSH, databases, and common resource problems.
Why Linux Error Logs Matter on a VPS
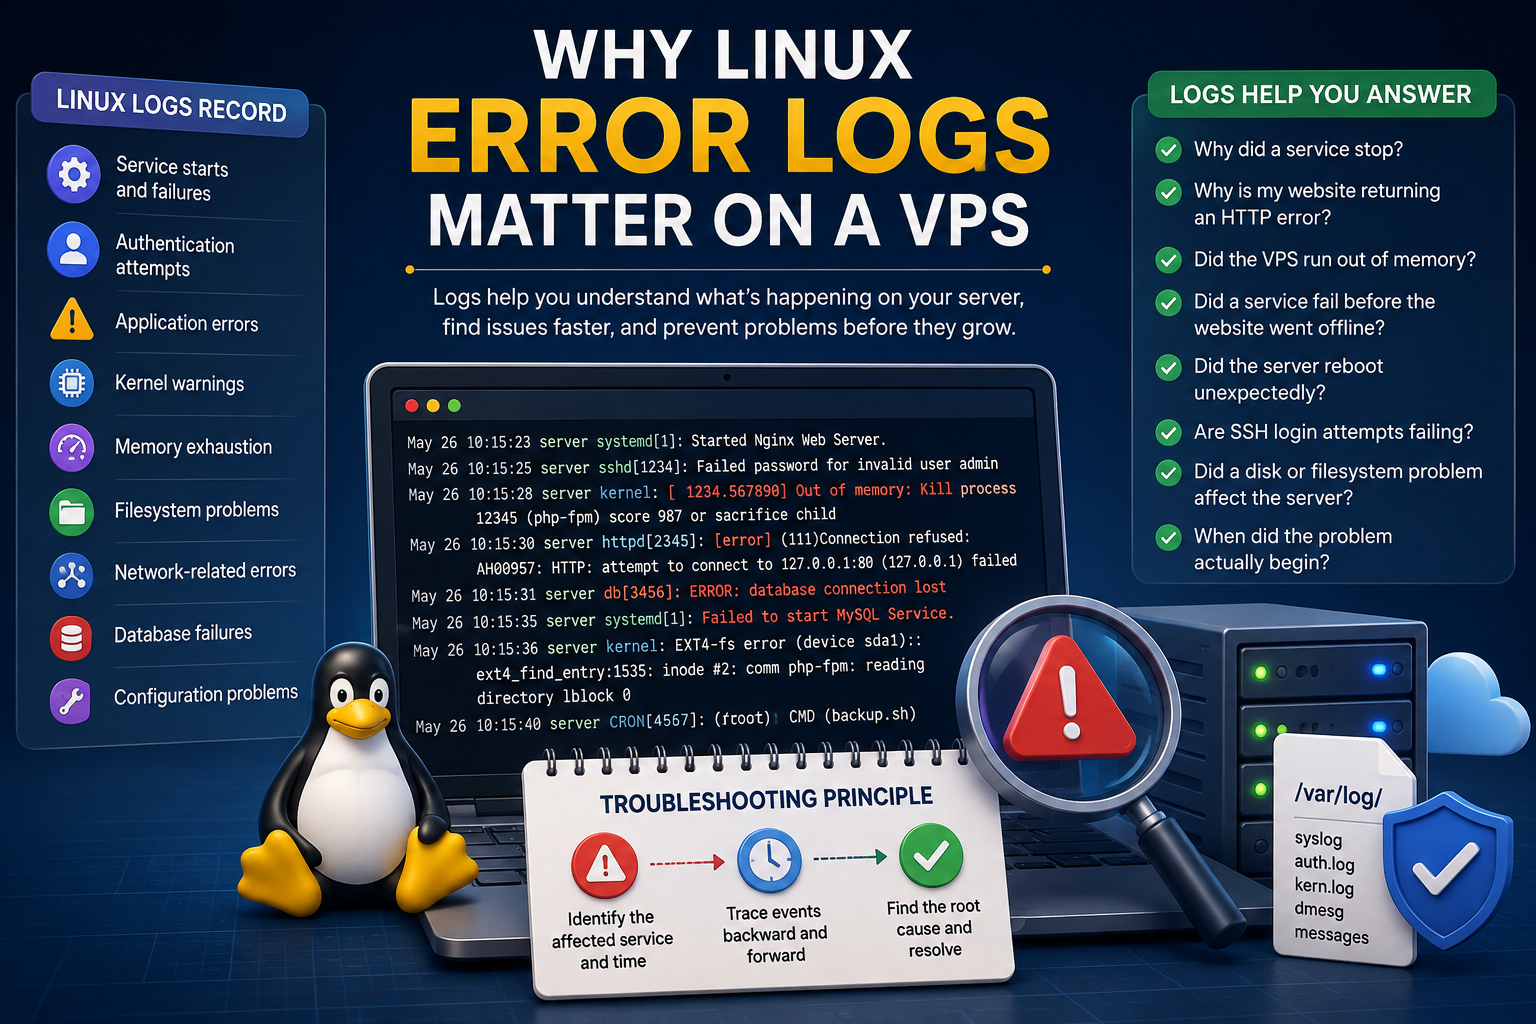
Linux services continuously record events such as:
- Service starts and failures
- Authentication attempts
- Application errors
- Kernel warnings
- Memory exhaustion
- Filesystem problems
- Network-related errors
- Database failures
- Configuration problems
Logs can help answer questions such as:
- Why did a service stop?
- Why is my website returning an HTTP error?
- Did the VPS run out of memory?
- Did a service fail before the website went offline?
- Did the server reboot unexpectedly?
- Are SSH login attempts failing?
- Did a disk or filesystem problem affect the server?
- When did the problem actually begin?
A useful troubleshooting principle is:
Start with the affected service and the approximate incident time, then trace related events backward and forward through the system.
This is usually much more effective than reading thousands of log entries from beginning to end.
Where Linux Logs Are Stored
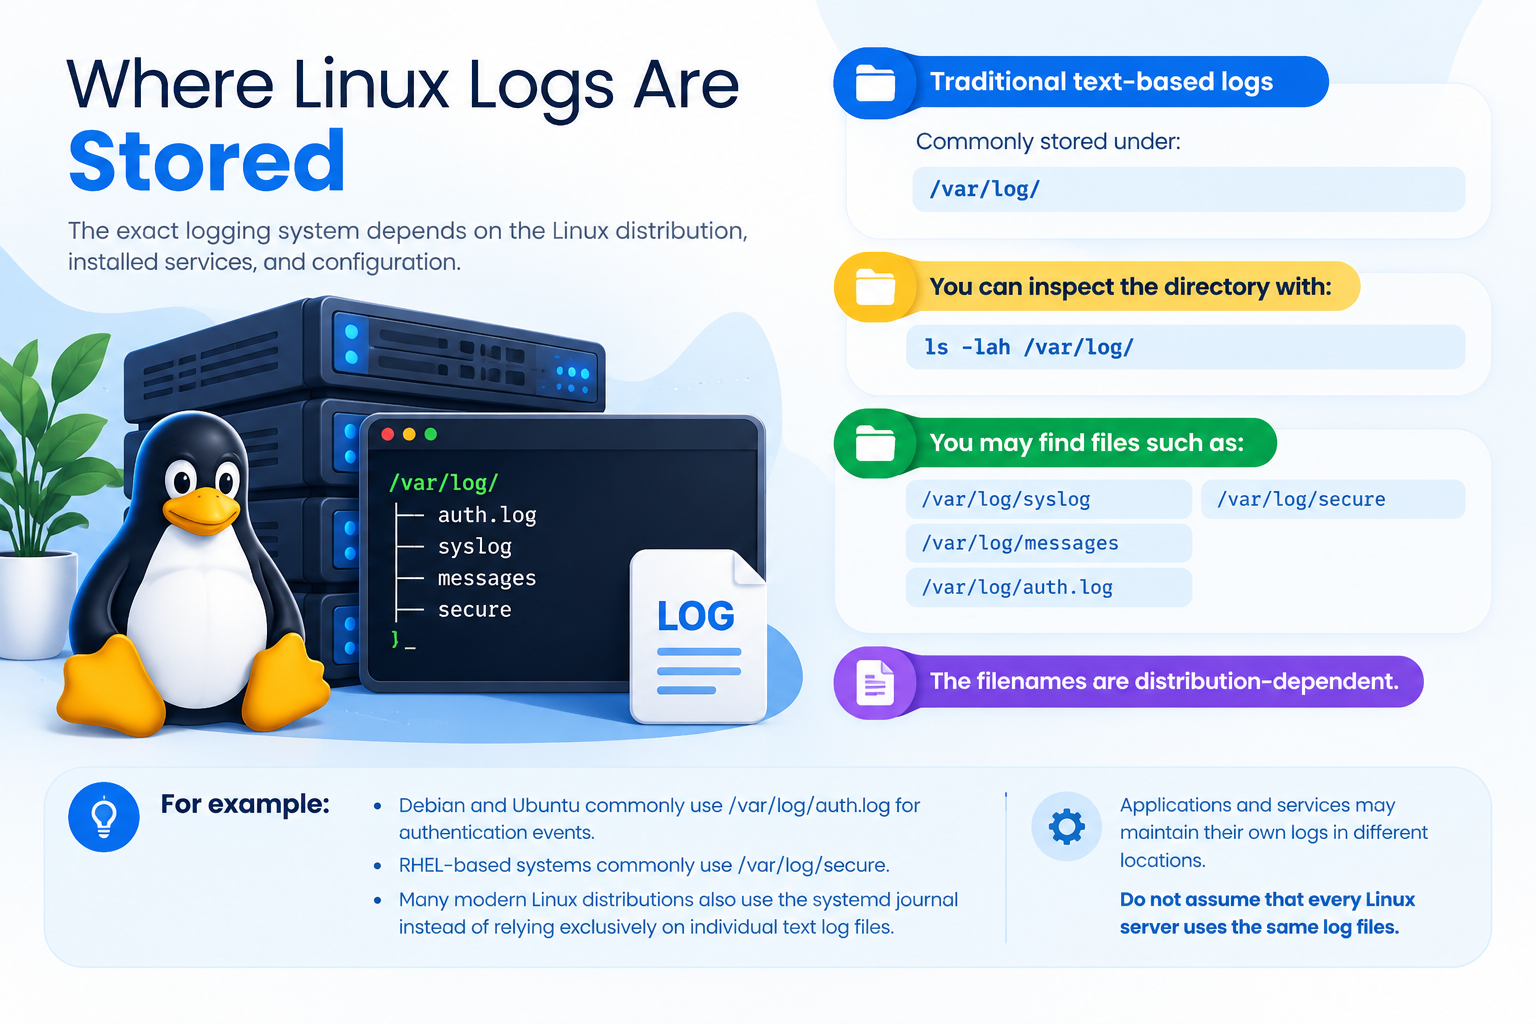
The exact logging system depends on the Linux distribution, installed services, and configuration.
Traditional text-based logs are commonly stored under:
/var/log/
You can inspect the directory with:
ls -lah /var/log/
You may find files such as:
/var/log/syslog
/var/log/messages
/var/log/auth.log
/var/log/secure
The filenames are distribution-dependent.
For example:
- Debian and Ubuntu commonly use /var/log/auth.log for authentication events.
- RHEL-based systems commonly use /var/log/secure.
- Many modern Linux distributions also use the systemd journal instead of relying exclusively on individual text log files.
Applications and services may maintain their own logs in different locations.
Do not assume that every Linux server uses the same log files.
Using journalctl to Read Linux Logs
Many modern Linux distributions use systemd, which provides the journalctl command for viewing the system journal.
To view journal entries:
journalctl
Because a busy VPS can generate a large amount of output, filtering the journal is usually more useful.
View the Most Recent Entries
journalctl -n 100
This displays the latest 100 journal entries.
To follow new entries as they appear:
journalctl -f
This is useful when reproducing a problem while watching the server logs in real time.
View Logs From the Current Boot
journalctl -b
This limits the output to the current boot.
This is especially useful when investigating a problem that appeared after a reboot.
Check Previous Boots
If your VPS restarted unexpectedly, you may want to determine what happened before the reboot.
First, list the boots retained by the journal:
journalctl –list-boots
You may see output identifying the current boot as 0 and an earlier boot as -1.
To inspect the previous boot:
journalctl -b -1
This only works when logs from the previous boot are available. Journal storage and retention depend on the server’s configuration.
Filter Logs by Time
Time filtering is one of the most effective ways to reduce noise.
For example:
journalctl –since “2026-08-27 10:30:00” –until “2026-08-27 10:50:00”
You can also use relative times:
journalctl –since “1 hour ago”
or:
journalctl –since “30 minutes ago”
For a production incident, narrowing the investigation to the period immediately before and after the failure can save significant time.
Check Logs for a Specific Service
If you know which service is affected, filter the journal by its systemd unit.
For Nginx:
journalctl -u nginx -n 100
For Apache on systems where the unit is named apache2:
journalctl -u apache2 -n 100
For MariaDB:
journalctl -u mariadb -n 100
For MySQL:
journalctl -u mysql -n 100
The exact service name depends on the distribution and installation.
You can combine service and time filters:
journalctl -u nginx –since “30 minutes ago”
This is often much more useful than searching the entire system journal.
How systemctl and journalctl Work Together
Two commands are particularly useful when troubleshooting systemd services:
systemctl status nginx
and:
journalctl -u nginx -n 100
They answer different questions.
systemctl status helps you understand the service’s current state.
journalctl helps you investigate what the service has been reporting.
For example, if Nginx is currently inactive, systemctl status nginx may show that the service failed. The journal can then provide the error that caused the failure.
A useful troubleshooting pattern is:
systemctl status SERVICE
journalctl -u SERVICE -n 100
Replace SERVICE with the actual service name.
How to Read a Linux Log Entry
A typical log entry contains several useful pieces of information.
For example:
Aug 27 10:42:15 server01 nginx[1254]: connect() failed while connecting to upstream
You can break it down into:
- Timestamp: Aug 27 10:42:15
- Hostname: server01
- Service: nginx
- Process ID: 1254
- Message: connect() failed while connecting to upstream
The message itself is important, but the surrounding events can be even more useful.
For example, an application might report:
Database connection failed
That does not necessarily mean the application caused the problem. The database service may have stopped earlier because of memory exhaustion, a configuration problem, or a storage issue.
This is why good log analysis focuses on relationships between events, not isolated messages.
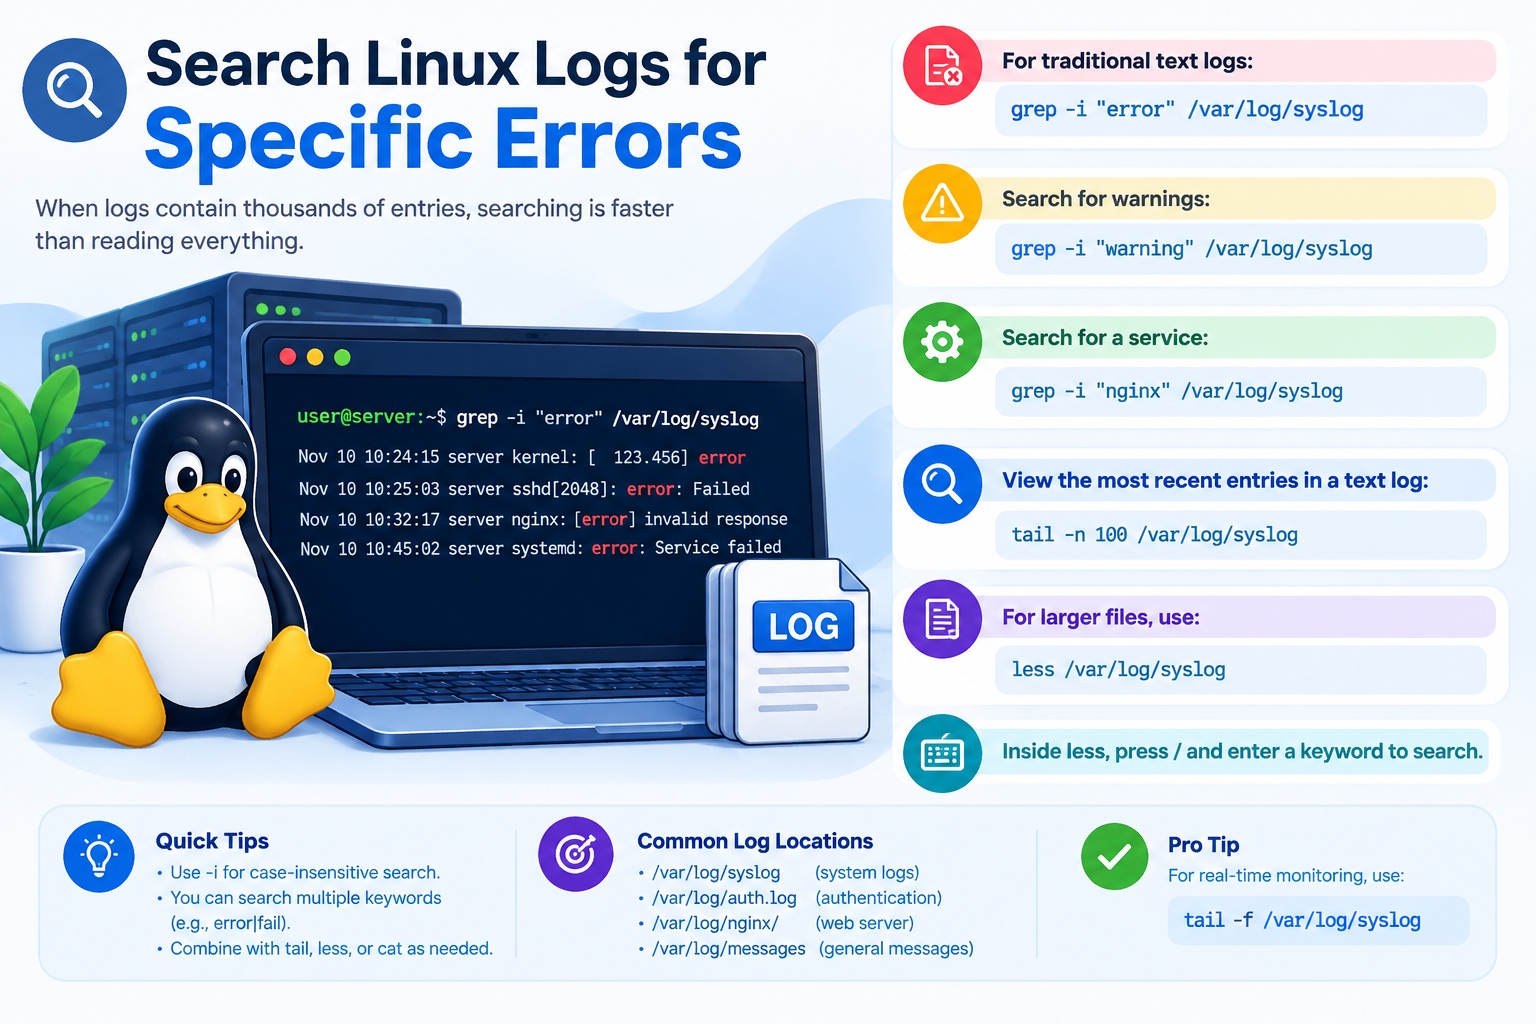
Search Linux Logs for Specific Errors
When logs contain thousands of entries, searching is faster than reading everything.
For traditional text logs:
grep -i “error” /var/log/syslog
Search for warnings:
grep -i “warning” /var/log/syslog
Search for a service:
grep -i “nginx” /var/log/syslog
View the most recent entries in a text log:
tail -n 100 /var/log/syslog
For larger files, use:
less /var/log/syslog
Inside less, press / and enter a keyword to search.
Search the Journal
You can also search journal output:
journalctl | grep -i “error”
For kernel-related events:
journalctl -k | grep -Ei “error|warning|failed”
Remember that searching for the word error is only a starting point. Important failures may be recorded with terms such as failed, timeout, denied, killed, refused, or unavailable.
Check Error Priorities with journalctl
You can filter journal entries by priority.
For example:
journalctl -p err -n 100
This shows recent messages with error-level priority.
You can also include warnings through errors:
journalctl -p warning..err -n 100
These commands are useful for quickly finding potentially important messages.
However, do not assume that every error-level message caused your problem. A message can be unrelated to the incident.
Always correlate the message with the affected service and the incident timeline.
Check Kernel Messages
Kernel messages can help diagnose low-level system problems involving memory, filesystems, devices, and networking.
On systems where dmesg is available:
sudo dmesg
For a focused search:
sudo dmesg | grep -Ei “error|warning|failed”
On systemd-based systems, you can also use:
journalctl -k
The journal approach is particularly useful when investigating events across different boots.
Depending on the server configuration, an unprivileged user may not be permitted to read the kernel buffer with dmesg.
Check for Out-of-Memory Errors
Memory exhaustion is a common cause of unexpected service failures on VPS servers.
Linux may invoke the OOM (Out-Of-Memory) killer when the system cannot satisfy memory demands.
Search kernel messages for OOM-related events:
journalctl -k | grep -Ei “oom|out of memory|killed process”
You can also search:
sudo dmesg | grep -Ei “oom|out of memory|killed process”
Messages indicating that a process was killed because of memory pressure are important evidence.
However, a slow VPS does not automatically mean that an OOM event occurred. High CPU usage, disk I/O, swap pressure, application problems, and network issues can produce similar symptoms.
If you find an OOM event, investigate:
- Which process was killed?
- How much memory was available?
- Was swap being used?
- Did memory usage increase before the failure?
- Did the same problem happen repeatedly?
Do not simply restart the affected service without investigating why memory became exhausted.
Check Disk Space and Filesystem Problems
A full filesystem can cause surprisingly broad failures.
For example, applications may be unable to create files, databases may fail, logs may stop being written, and services may refuse to start.
Check disk usage with:
df -h
Also check inode usage:
df -i
If the filesystem is full, look for large directories or files before deleting anything.
You can also check how much space the systemd journal is using:
journalctl –disk-usage
Filesystem-related kernel messages can be investigated with:
journalctl -k | grep -Ei “filesystem|I/O error|disk|ext4|xfs”
Do not delete logs or system files blindly just to free disk space. First determine what is consuming the storage and whether it can be safely removed.
Check SSH Authentication Logs
If you are investigating SSH login problems or unexpected authentication activity, check the authentication logs.
On systems using /var/log/auth.log:
grep -i “ssh” /var/log/auth.log
Search for failed authentication:
grep -i “failed” /var/log/auth.log
On systems using /var/log/secure:
grep -i “failed” /var/log/secure
You can also use the system journal.
Depending on the distribution, the SSH service may be named ssh or sshd:
journalctl -u ssh –since “1 hour ago”
or:
journalctl -u sshd –since “1 hour ago”
When investigating authentication activity, pay attention to:
- Timestamp
- Username
- Source IP address
- Authentication result
- Whether the login was accepted or rejected
- Whether the activity matches expected administration
Internet-facing SSH servers commonly receive automated failed login attempts. A failed login alone does not prove that a VPS has been compromised.
Unexpected successful authentication or other correlated suspicious activity deserves much more attention.
Check Nginx and Apache Error Logs
When a website is unavailable, the web server’s own logs are often more useful than the general system log.
For Nginx, commonly used files include:
/var/log/nginx/error.log
/var/log/nginx/access.log
For Apache:
/var/log/apache2/error.log
/var/log/apache2/access.log
These are common locations, not universal ones. Virtual hosts and custom configurations may use different paths.
For example:
tail -n 100 /var/log/nginx/error.log
When investigating a website problem, compare the timestamps in the web-server logs with application, PHP-FPM, database, and system logs.
This can help determine where the failure originated.
Check PHP-FPM Logs
For PHP-based applications such as WordPress, PHP-FPM can be an important part of the troubleshooting chain.
First check the service:
systemctl status php8.3-fpm
Then inspect its journal:
journalctl -u php8.3-fpm -n 100
The exact PHP-FPM service name depends on the installed PHP version and distribution.
If a website returns a 502 or 504 error, check whether PHP-FPM is:
- Running
- Restarting repeatedly
- Unable to create workers
- Running out of resources
- Reporting configuration errors
- Failing to communicate with the web server
Check MySQL or MariaDB Logs
Database failures can appear to the user as website or application errors.
Check the database service status:
systemctl status mysql
or:
systemctl status mariadb
Then inspect recent logs:
journalctl -u mysql -n 100
or:
journalctl -u mariadb -n 100
Look for events around the time the application started failing.
A useful troubleshooting chain can be:
Website error → Web server log → PHP-FPM log → Database log → System/kernel log
This helps you move from the visible symptom toward the underlying cause.
Practical Example: Troubleshooting an HTTP 502 Error
Suppose a website suddenly starts returning:
502 Bad Gateway
Do not immediately restart every service.
Start by checking the web server:
systemctl status nginx
Then review recent Nginx events:
journalctl -u nginx –since “15 minutes ago”
Check the Nginx error log:
tail -n 100 /var/log/nginx/error.log
If the log indicates an upstream or PHP-FPM problem, check PHP-FPM:
systemctl status php8.3-fpm
Then:
journalctl -u php8.3-fpm –since “15 minutes ago”
If PHP-FPM or another service appears to have been killed because of memory pressure, investigate:
journalctl -k | grep -Ei “oom|out of memory|killed process”
Then check current resource conditions:
free -h
df -h
The goal is not simply to make the 502 disappear. The goal is to determine why the upstream service became unavailable.
Look for the First Meaningful Failure
A common troubleshooting mistake is investigating only the final error.
You might see:
Application error
Database connection failed
Database service unavailable
Out of memory
The application error is probably a symptom.
The database failure may also be a symptom.
The out-of-memory event may be closer to the actual cause.
When reviewing logs, ask:
- What was the first unusual event?
- Which service was affected?
- Did another service fail before it?
- Was there a system-level warning?
- Did memory, disk, CPU, or another resource become exhausted?
- Did the same sequence happen previously?
This approach helps you identify the root cause instead of repeatedly treating symptoms.
Don’t Treat Every Warning as the Cause
Linux servers generate informational messages and warnings during normal operation.
Seeing:
WARNING
does not automatically mean you have found the cause of an outage.
Before acting on a log message, ask:
- Did it occur around the same time as the incident?
- Does it involve the affected service?
- Does the message repeat?
- Is there a related failure immediately before or after it?
- Can the event be reproduced?
- Does other evidence support the same conclusion?
Avoid changing configuration simply because one alarming-looking message appeared in a log.
A Practical VPS Log Troubleshooting Workflow
When a VPS problem occurs, follow a consistent process.
1. Record the Symptoms
Write down what is actually failing.
Examples include:
- Website unavailable
- HTTP 500 or 502 error
- SSH connection failing
- Database unavailable
- Application crashing
- Server becoming extremely slow
- VPS unexpectedly rebooting
2. Identify the Affected Service
Determine whether the issue involves:
- Nginx
- Apache
- PHP-FPM
- MySQL/MariaDB
- SSH
- Docker
- Another application or system service
3. Check the Current Service State
systemctl status SERVICE
4. Read Recent Service Logs
journalctl -u SERVICE -n 100
5. Narrow the Time Window
journalctl -u SERVICE –since “30 minutes ago”
6. Check Application and Web-Server Logs
Look at the relevant application, Nginx, Apache, PHP-FPM, or database logs.
7. Check System Resources
For memory:
free -h
For disk space:
df -h
For inode usage:
df -i
8. Check Kernel Events
journalctl -k
Look specifically for OOM, filesystem, I/O, or other system-level errors.
9. Correlate the Timeline
Compare timestamps across the different logs.
10. Make One Evidence-Based Change
Avoid changing multiple settings at once.
Make the smallest reasonable correction based on the evidence, then test the service again.
11. Monitor After the Fix
Use tools such as:
journalctl -f
or:
tail -f /var/log/nginx/error.log
to determine whether the problem returns.
Common Mistakes When Reading VPS Logs
Reading Everything
Large logs contain enormous amounts of routine activity.
Better approach: filter by service, keyword, boot, and time.
Focusing Only on the Word “Error”
Important failures can appear as failed, timeout, denied, killed, refused, or other messages.
Better approach: examine the surrounding events.
Ignoring Timestamps
A message from several hours earlier may have nothing to do with the current outage.
Better approach: establish when the problem started and investigate around that period.
Changing Configuration Too Quickly
Changing several settings before understanding the problem makes troubleshooting harder.
Better approach: collect evidence first.
Checking Only One Log
A website failure can involve multiple services.
Better approach: trace the dependency chain.
Ignoring Resource Exhaustion
CPU, memory, disk space, and inode exhaustion can cause apparently unrelated service failures.
Better approach: check system resources when the service logs do not provide an obvious explanation.
Repeatedly Restarting Services
A restart can temporarily hide the symptom without fixing the cause.
Better approach: determine why the service failed before repeatedly restarting it.
When Logs Are Rotated or Missing
Linux systems commonly rotate logs to prevent them from consuming excessive disk space.
You may therefore see files such as:
syslog
syslog.1
syslog.2.gz
or similar files depending on the distribution and log rotation configuration.
List the available logs:
ls -lah /var/log/
For compressed logs, zgrep can search without manually extracting the file:
zgrep -i “error” /var/log/syslog.2.gz
If a journal entry from a previous boot is missing, check:
journalctl –list-boots
If older boots are not listed, the journal may not have been configured to retain them, or the relevant data may already have been removed according to the server’s retention policy.
When to Escalate a VPS Problem
Logs are powerful, but they cannot resolve every problem by themselves.
Consider getting experienced server assistance when:
- The root cause remains unclear after reviewing relevant logs.
- The VPS repeatedly crashes or becomes unreachable.
- Filesystem or disk errors appear.
- Multiple services fail simultaneously.
- You suspect a security incident.
- Important production data may be at risk.
- A configuration change could cause further downtime.
- You are not confident about the impact of a proposed fix.
Before making major changes, preserve relevant logs and record the time of the incident. This evidence can be valuable when another administrator or support team needs to investigate the problem.
Quick Linux Log Commands Cheat Sheet
|
Task |
Command |
|
View recent journal entries |
journalctl -n 100 |
|
Follow live journal entries |
journalctl -f |
|
View current boot |
journalctl -b |
|
View previous boot |
journalctl -b -1 |
|
List available boots |
journalctl –list-boots |
|
View service logs |
journalctl -u SERVICE |
|
View recent service logs |
journalctl -u SERVICE -n 100 |
|
Filter by time |
journalctl –since “1 hour ago” |
|
Show error-level messages |
journalctl -p err -n 100 |
|
Show kernel messages |
journalctl -k |
|
Check service status |
systemctl status SERVICE |
|
View kernel buffer |
sudo dmesg |
|
Check memory |
free -h |
|
Check disk space |
df -h |
|
Check inode usage |
df -i |
|
Check journal size |
journalctl –disk-usage |
|
Search text logs |
grep -i “keyword” /path/to/log |
|
Search compressed logs |
zgrep -i “keyword” /path/to/log.gz |
|
Follow a text log |
tail -f /path/to/log |
FAQ

The author
Asher Feroze
CEO (Vertisols.com)